 Illustration
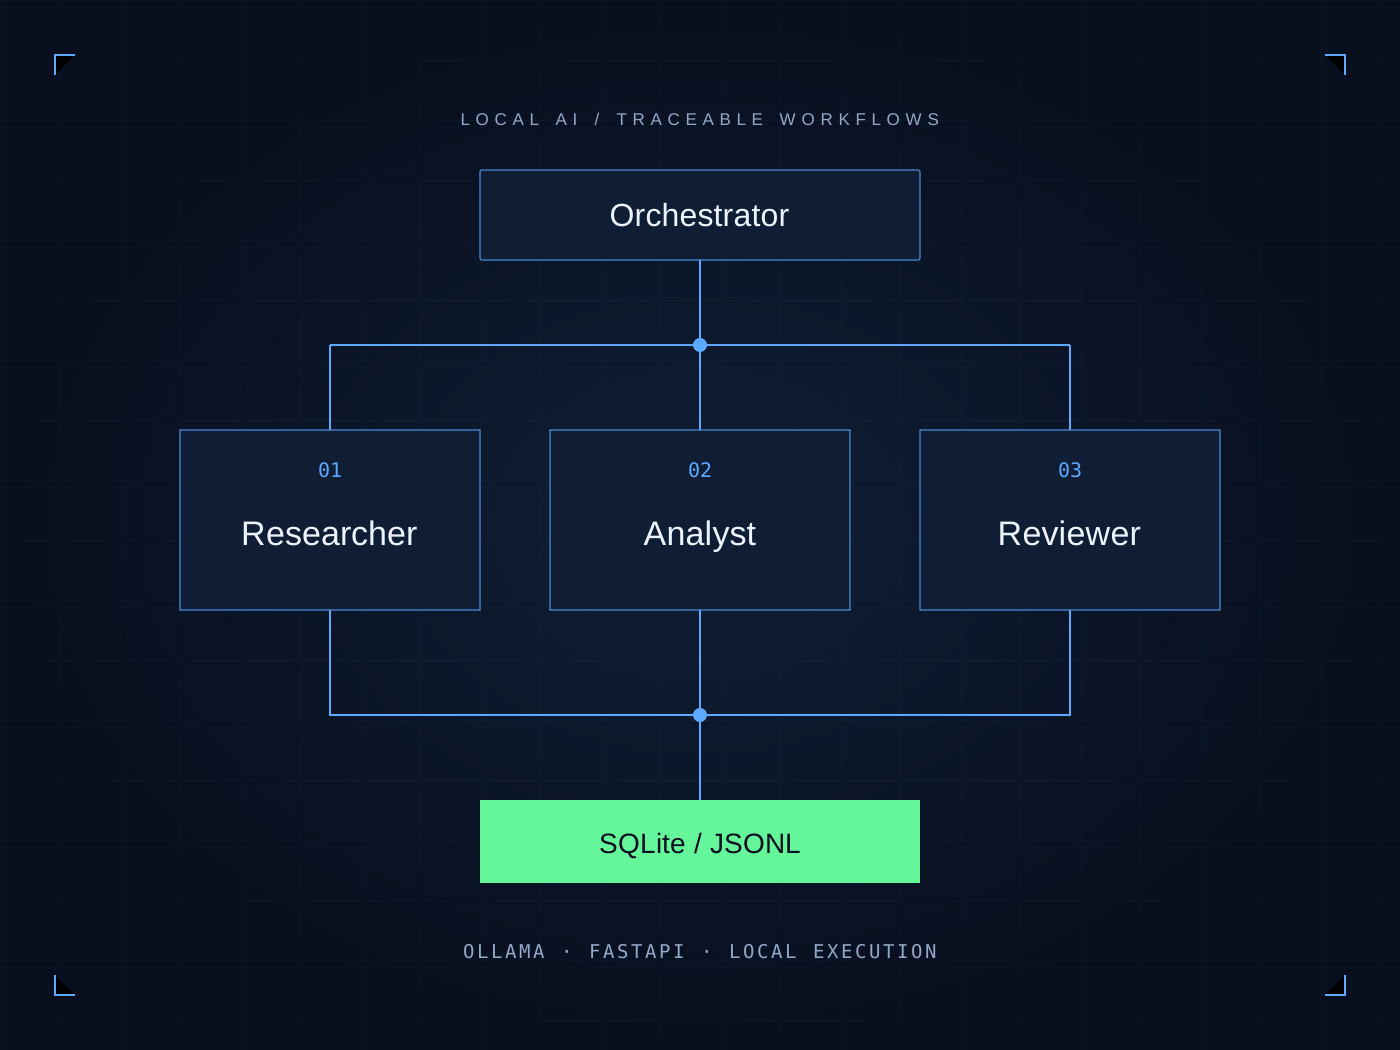
AI with a paper trail.
A local multi-agent system that makes evidence, review and execution traces part of the workflow.
Explore the projectAI / Reinforcement learning
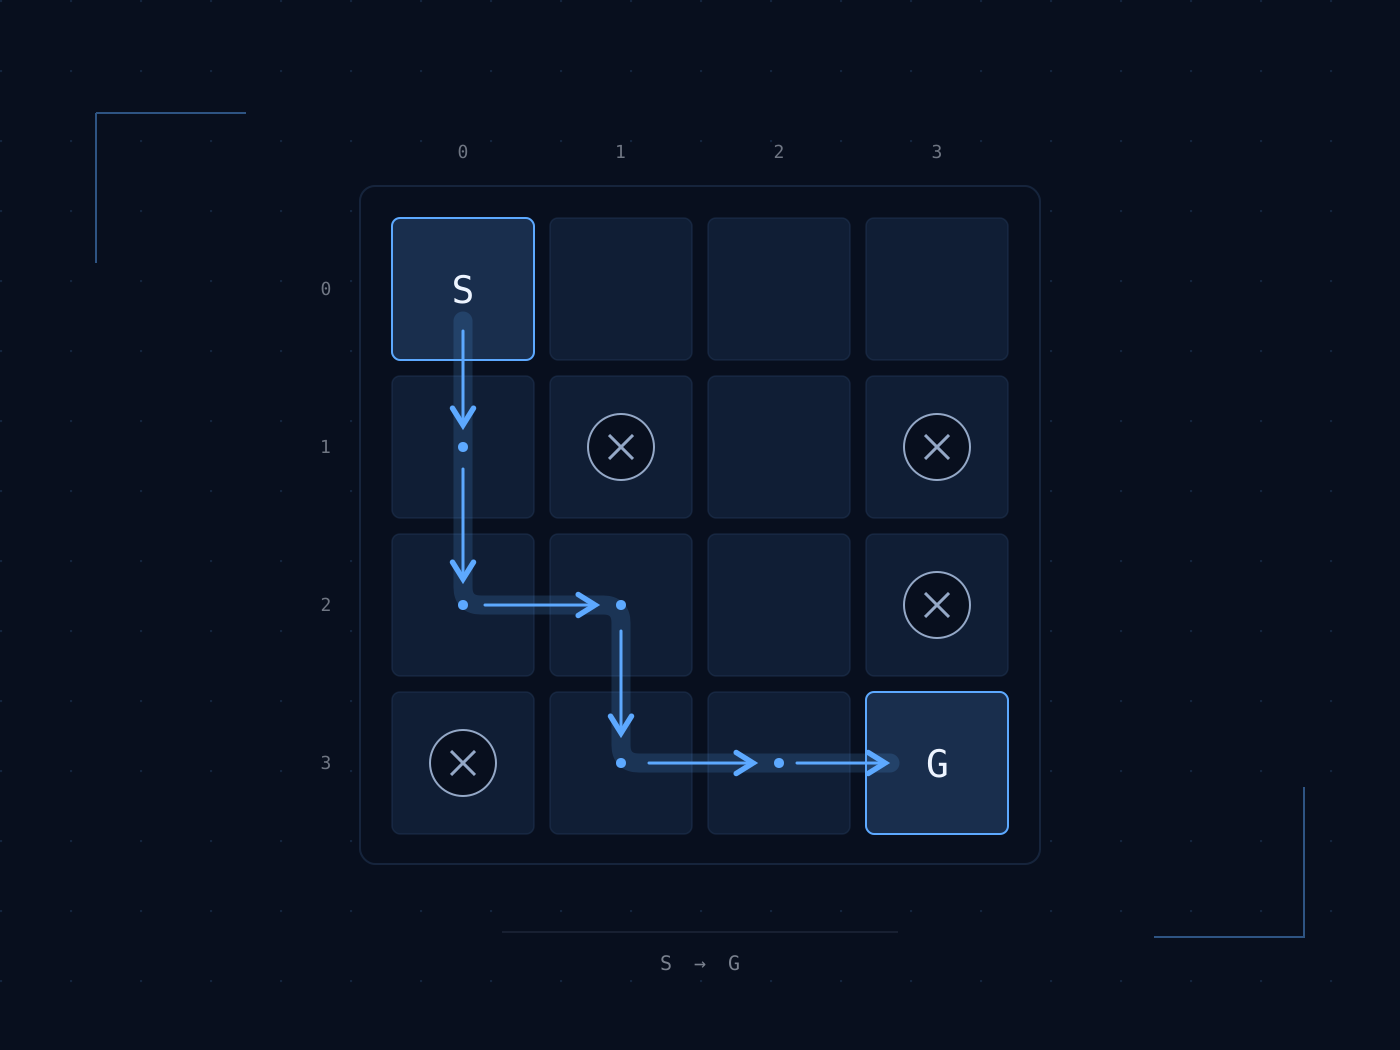
Comparing a Q-table and a deep Q-network in the FrozenLake environment.
01 / The challenge
Understand how exploration, reward design and value representation affect learned behaviour.
An educational exploration of how an agent learns from rewards. Two approaches solve the same grid-world task: tabular Q-learning stores state/action values directly, while a PyTorch neural network approximates them.
02 / The approach
Compare tabular Q-learning with a neural deep Q-network in the same environment.
Use reward shaping and an exploration schedule; add replay memory and a target network for the DQN.
Track training rewards and exploration, then visualise evaluation results.
03 / Outcomes
04 / Scope & next steps
The baseline is sourced from johnnycode8/gym_solutions. The other learning scripts adapt that work with modified rewards, validation and visualisation; attribution is preserved in the repository.
Continue exploring